Third-party model evaluations are the most reliable safeguard against AI failures in regulated industries. The failures that matter most are precisely the ones your internal team is designed to overlook.
When an LLM developer updated a fine-tuning dataset built by their in-house team, what looked like a routine model improvement produced a nearly 5X increase in a specific error type. Understanding why AI systems fail in production matters, but catching that failure before it reaches production requires independent evaluation. In healthcare, financial services, or insurance, catching that error type before go-live is not a quality preference; it is a regulatory and reputational requirement.
Internal evaluation teams are structurally ill-suited to catch the failures most likely to cause harm in regulated industries; the gap between what they test and what matters is widest exactly where risk is highest.
Two dynamics drive this. Confirmation bias means teams test for failure modes they expect, so known weaknesses get addressed and unknown ones go undetected. Benchmark dependency compounds the problem: industry benchmarks measure average performance across a broad task distribution, not edge-case performance on your specific data distribution and regulatory context. A model that scores well on standard benchmarks may still fail on the domain-specific prompts your users submit in production.
Beyond the testing gaps, internal evaluations lack external credibility. When regulators, auditors, or a board risk committee asks how you know your model is compliant and reliable, internal testing alone rarely satisfies the inquiry. Independent validation provides the audit trail and external credibility that self-assessment cannot. AI systems deployed without that independent check are significantly more likely to generate biased outputs or fail under distribution shift as the model encounters new behaviors at production scale.
A rigorous third-party model evaluation addresses six risk categories that regulated organizations cannot afford to leave untested: reputational risk, regulatory compliance, bias and fairness, reliability, security, and transparency and explainability.
Reputational risk covers what happens when a model produces outputs that, while not technically incorrect, create trust problems with clients, partners, or regulators. In regulated industries, a single high-profile AI failure including a biased insurance denial, an incorrect medical coding suggestion, or a discriminatory lending decision can generate press coverage that accelerates regulatory scrutiny and damages business relationships.
Regulatory compliance evaluation documents how well your model satisfies the specific requirements you operate under: HIPAA in healthcare, Fair Lending and FDIC guidance in financial services, state insurance commission standards in insurance. Third-party evaluation produces the documentation an auditor can examine, not just a model card your development team authored.
Bias and fairness testing goes beyond checking for disparate impact on protected classes. It covers distributional fairness across the edge cases most likely to appear in your deployment context, including non-standard input formats and adversarial prompts that expose gaps between stated model behavior and actual behavior.
Reliability evaluation covers model robustness testing under distribution shift and performance degradation, characterizing what fails and under what conditions.
Security testing evaluates prompt injection vulnerabilities and data leakage risks, along with how the model responds to adversarial inputs designed to surface those gaps. AI red teaming is the adversarial component: using real-world attack techniques to expose vulnerabilities that standard safety testing does not catch.
Transparency and explainability evaluation assesses whether the model's decision-making process can be documented in terms a compliance team or court can follow, and confirms that actual model behavior matches its stated design intent.
Generic benchmarks measure average model performance across standardized tasks; custom evaluations measure your model's performance on your data, your use cases, and your compliance requirements — and that is the only measurement that matters when your deployment context is what is at risk.
Invisible's research on the AI evaluation crisis documents how the gap between benchmark performance and production behavior has become a material business risk for enterprise AI teams. A model can score well on industry benchmarks while failing on the specific input distributions it encounters in production. In regulated industries, those production failures carry consequences that a benchmark score cannot absorb.
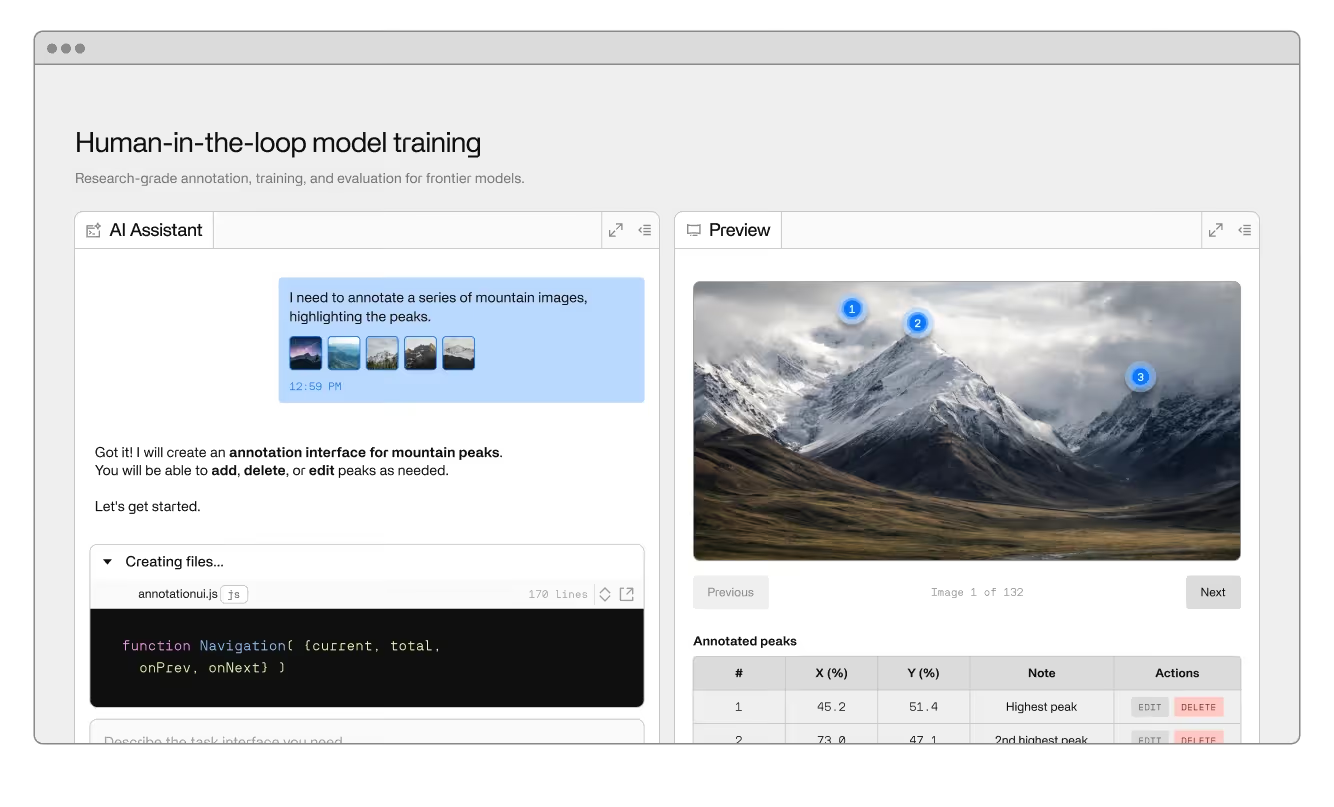
Custom evaluations also provide a direct path to remediation. When a third-party evaluation identifies a failure mode, the diagnosis should be specific enough to drive action: whether the problem traces to a dataset artifact or a model architecture limitation. A complete enterprise AI model evaluation covers both the diagnostic and the remediation path, not just the identification of problems.
The evaluation method matters too. Offline evaluation, which tests against a held-out dataset before deployment, catches known failure modes. Online evaluation, meaning continuous monitoring of live outputs against quality signals, catches the failure modes that only emerge at production scale. Effective evaluation programs use both, with human-in-the-loop review for the tasks and failure modes that automated metrics cannot fully assess.
Third-party evaluation finds what internal testing misses, not because internal teams are incompetent, but because they are optimized to test for what they expect the model to do wrong rather than what it will actually do wrong in production.
When one LLM developer partnered with Invisible to evaluate a model update, the engagement began with a snapshot assessment: a systematic review of the current model's performance across the task distribution it was expected to handle in production. That assessment identified a nearly 5X increase in a specific error type relative to the previous model version, an error the developer's internal evaluation process had not been designed to catch.
Tracing the failure to its root cause required going deeper than output analysis. Invisible's evaluation team examined the fine-tuning dataset built by the developer's in-house team and identified the dataset artifacts driving the error spike. The fix required a targeted human-generated dataset, built by Invisible's AI training specialists to address the specific gap, that became the basis for a corrective fine-tuning run. The error pattern resolved.
The outcome illustrates the core value of third-party evaluation: catching problems and tracing them to actionable causes that an internal team, evaluating its own work, was not positioned to find.
Regulated industries cannot afford to discover AI failures after deployment. Learn how Invisible's AI training and evaluation capabilities help enterprise teams validate models before they reach production, and get started with an evaluation scoped to your use case.
A third-party model evaluation is an independent assessment of an AI model's performance and compliance conducted by a party with no stake in the outcome. It finds failure modes the development team did not anticipate, including biased outputs and patterns that only emerge in production. It also produces the independent documentation regulators and auditors require.
Internal testing is optimized around known failure modes — the problems teams expect their model to have. Third-party evaluation is designed to surface failure modes the development team did not know to look for. Independent evaluators bring fresh testing criteria and no confirmation bias, along with the external credibility that regulators and auditors require.
Third-party evaluations address six risk categories: reputational failures, regulatory compliance gaps, bias and fairness problems, reliability issues, security vulnerabilities, and transparency deficits. Custom evaluations designed around your specific data distribution and use case consistently identify failure modes that generic benchmarks miss because they were not designed to look for them.
At minimum, evaluate before any production deployment and after any significant model update. For regulated industries, ongoing monitoring between formal evaluation cycles is standard practice. Models in healthcare, financial services, or insurance should be evaluated on a cadence that reflects the pace of change in their deployment environment, including shifts in underlying data distribution and regulatory context.
A complete evaluation includes a snapshot assessment against held-out data, failure mode characterization across your specific task distribution, bias and fairness testing, and prompt injection evaluation. Critically, it should include a root-cause analysis tying each identified failure to an actionable remediation path: whether that requires new training data or a model architecture adjustment.
Yes. Third-party evaluations produce independent testing documentation and failure mode analyses that self-assessment cannot provide. Regulated industries increasingly incorporate this documentation into their AI governance programs. Some regulatory frameworks explicitly reference independent validation as a compliance mechanism.
Any model where errors carry regulatory exposure, patient harm potential, or reputational risk needs independent evaluation before go-live. Models that have undergone significant updates, are experiencing performance drift in production, or are being extended to a new deployment domain also warrant third-party assessment.